Every box is a
human decision.
Annotation, model evaluation and RLHF — delivered by identity-verified people, scored against a threshold you set, with the numbers attached to every delivery.
Verified workforce · 4-layer review · NDA & DPA on request
Six service lines, one standard.
Every line runs on written guidelines, calibrated reviewers and the same four-layer quality process.
Data annotation
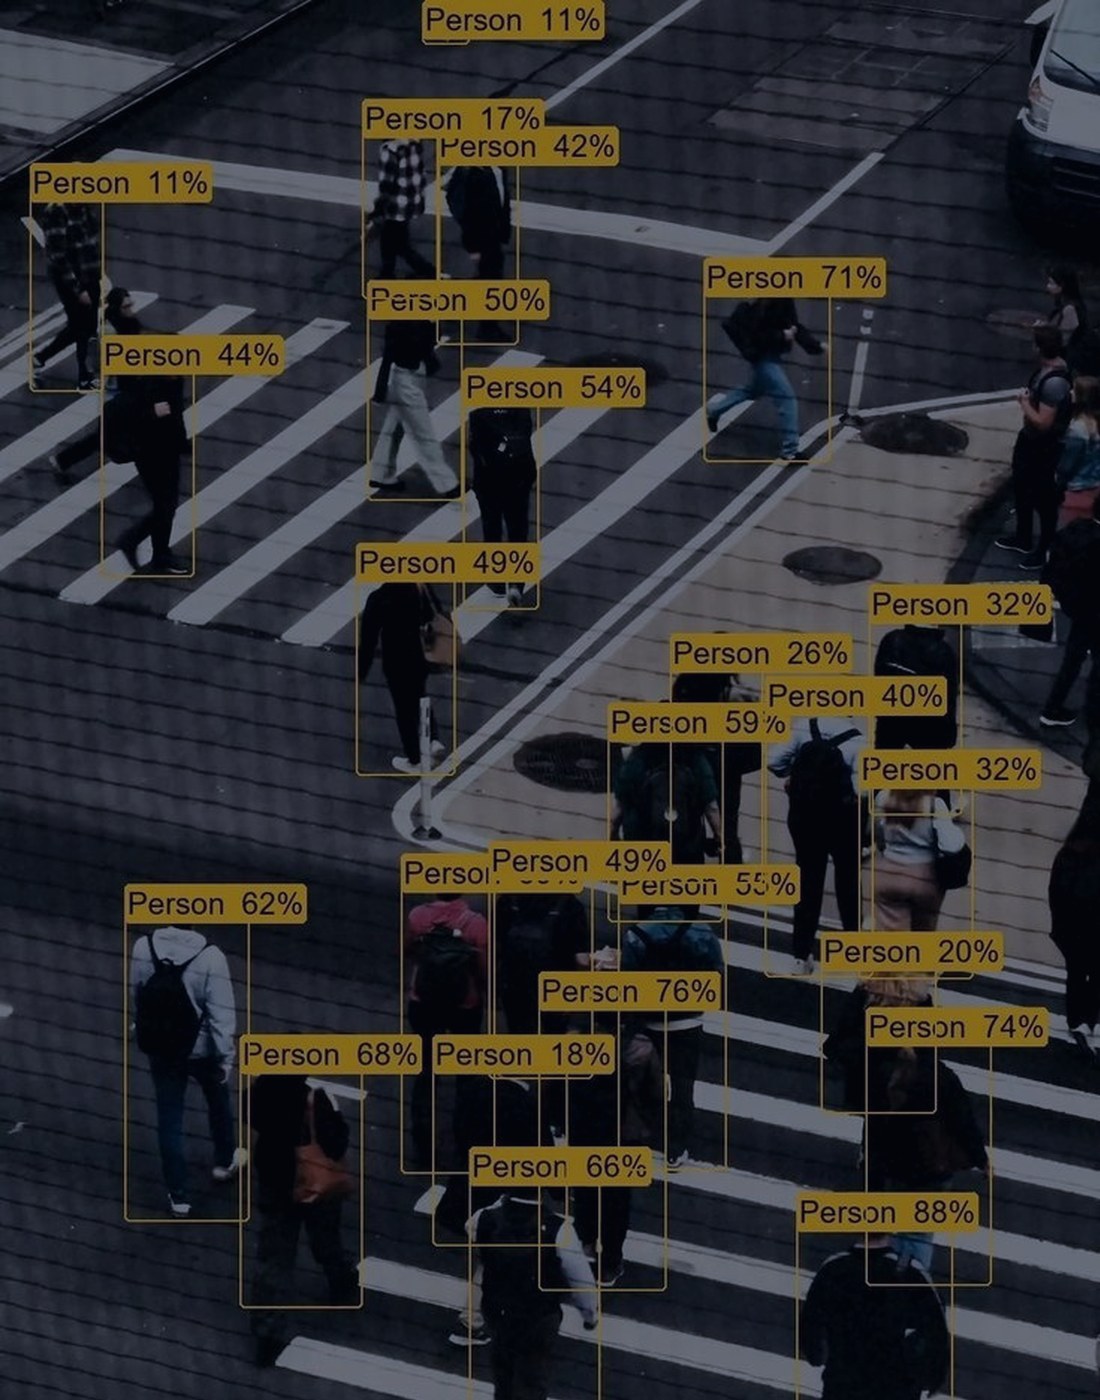
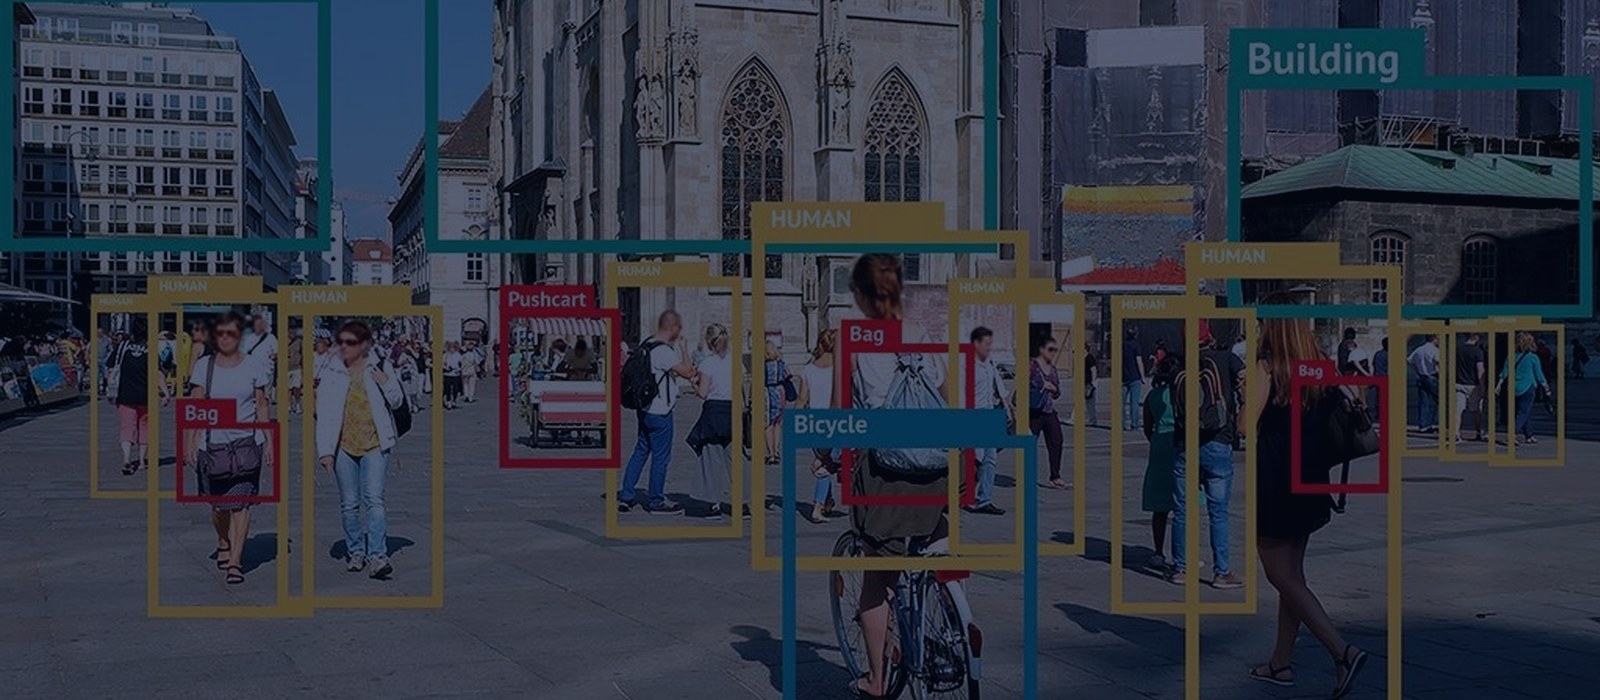
Image, video, text, audio and document labelling — bounding boxes, segmentation, keypoints, NER.
Model evaluation
Response rating, preference ranking, hallucination detection, instruction-following and safety review.
RLHF
Structured human feedback: ranking outputs, comparing candidates, writing ideal responses.
Dataset QA
Independent audit of an existing dataset — sampling, accuracy measurement, error taxonomy.
Content moderation
Text, image and video review against your policy and community guidelines.
Human-in-the-loop
Live monitoring, edge-case review and decision verification during deployment.
Six stages. Same every time.
Consult
Objectives, guidelines and the accuracy threshold, agreed with you.
Match
Contributors selected on skill, language and accuracy record.
Produce
Work executed in your platform or ours, to written guidelines.
Assure
Independent QA against gold tasks and sampled output.
Validate
Senior review on complex and high-value items.
Deliver
Secure handoff with the full quality report.
You get the numbers,
not just the output.
We're early, and we don't ask anyone to take our word for it. Every engagement starts with a paid pilot scored against a threshold agreed in advance.
Four layers before anything ships
- Contributor self-review against the project checklist
- Independent QA by someone who didn't do the work
- Senior validation on complex or high-value items
- Your acceptance review against the agreed threshold
In every delivery report
- Accuracy achieved against the threshold
- Items reviewed and inter-reviewer agreement
- Every error found, categorised by cause
- What changed in the guidelines as a result
Careless labels teach
confident mistakes.
The answers your security team wants.
Access control
- Role-based access, scoped to one project
- Need-to-know assignment — no blanket dataset access
- Named, identity-verified individuals, never an anonymous crowd
- Access logs kept for the engagement
Contracts
- Mutual NDA before any data moves
- DPA available on request
- Individual NDA signed by every contributor
- IP in all work product assigned to you
Data handling
- We work inside your platform where you have one
- Encrypted transfer and storage, approved tools only
- No copying, screenshots or off-platform storage
- Retention and deletion to your terms, confirmed in writing
Regulatory
- Handling aligned to the Nigeria Data Protection Act 2023
- Confidentiality obligations agreed with every contributor
- Documented incident reporting and escalation
- Sensitive-content projects scoped with worker welfare in mind
Start small. Scale when we've earned it.
We quote after seeing a data sample, never before — a number given blind is a number we'd have to revise.
Pilot
- A scoped sample of your real workload
- Guidelines built with your team
- Full quality report on delivery
- No obligation to continue
Project delivery
- Defined batch, deadline and threshold
- Named project manager and reviewer
- Quality report with every delivery
- Milestone-based invoicing
Dedicated team
- A consistent team that learns your domain
- Agreed capacity and turnaround SLA
- Quarterly reviews
- Priority scaling as volume grows
Invoicing in USD or NGN · Bank transfer, Wise or Payoneer
Tell us what you're
trying to train.
Send a short brief and a data sample. You'll get a written quote with a committed accuracy threshold, usually within one business day.
Fair questions.
You're new. Why trust you with our data?
Don't, on faith. Every engagement starts with a paid pilot on a scoped sample, measured against a threshold agreed in advance, with a full quality report on delivery. You risk one small batch. A mutual NDA is signed before any data moves, and our founder has worked hands-on inside the AI annotation industry across multiple training platforms.
What does it cost?
It depends on task complexity, volume, turnaround and security requirements — which is why we ask for a sample first. Send one and you'll get a written quote with a committed accuracy threshold.
Do we have to use your tools?
No. If you have your own platform, our team works inside it — usually the cleanest option for your security team. Where you don't, we supply and configure the tooling.
How do you actually measure quality?
Four mechanisms in parallel. Gold tasks: known-answer items seeded invisibly into each queue for an objective score. Random sampling: 20% of a new contributor's output, dropping to 5% once proven. Overlap: the same items given to several people, to measure agreement. Error taxonomy: every error categorised, so an individual accuracy problem is distinguishable from an ambiguous-guidelines problem.
Who exactly does the work?
Named, identity-verified individuals who passed a skills assessment in the relevant area, were briefed on your guidelines and signed an individual NDA. We can tell you who worked on your project and what they scored.
How fast can you start and scale?
A pilot typically starts within days of guidelines being agreed. Scaling is deliberate — we add people who have passed calibration on your specific guidelines, not whoever is free. We'd rather give you a realistic ramp than miss a deadline.
Can you handle sensitive or regulated data?
Tell us the requirements before the pilot and we'll scope to them — restricted access, work performed only in your environment, specific retention and deletion terms, a DPA. Where something is beyond what we can meet today, we'll say so rather than discover it mid-project.